Industrial downtime rarely has one simple cause. A failed bearing, a leaking air line, an overheated motor, or a missing replacement part can stop production, but the underlying issue is often a weak maintenance process. Teams looking to make reliability work more predictable can find out more about practical uptime-focused support while building stronger routines inside their own facilities.
The most effective approach is not to respond to every breakdown faster. It is to identify which assets matter most, detect changing conditions early, prepare for likely failures, and complete maintenance safely. The following steps provide a practical framework for reducing avoidable interruptions without treating every piece of equipment as equally critical.
Why Downtime Keeps Returning
When the same asset fails repeatedly, replacing the failed component may restore production without addressing the underlying cause. Poor lubrication, contamination, overheating, vibration, misalignment, loose electrical connections, and inconsistent inspections are common contributors to recurring trouble. A work order should capture not only what was replaced, but also the operating condition found and the likely cause.
Consider a pump with repeated seal failures. Installing a new seal may be necessary, yet pipe strain, dry running, excessive vibration, or an incorrect operating point can damage the replacement just as quickly. A basic root-cause review helps the team move beyond the immediate repair and determine what must change to prevent another interruption.
See also: Regain Control of Your Life With Drug Addiction Treatment
Build a Risk-Based Maintenance Plan
Not every asset deserves the same inspection frequency, spare-parts coverage, or engineering attention. Rank equipment by practical risk, then match the maintenance effort to the consequence of failure. Useful ranking questions include:
- Could failure create a safety or environmental hazard?
- Would it stop a production line or constrain output?
- What would repair, lost material, and recovery require?
- Is backup equipment available and ready to use?
- Has the asset failed before, and does it have a repeat pattern?
- How long would it take to restore service?
Group assets as critical, important, or low risk. Critical assets warrant documented condition checks, clear response plans, and carefully managed spares. Important assets require planned maintenance, while low-risk equipment often receives simpler routine care. This approach directs limited labor toward the failures that would matter most.
Use Preventive and Predictive Maintenance Together
Preventive maintenance is planned work performed at set intervals, such as lubrication, cleaning, inspection, adjustment, or replacement of known wear items. Predictive maintenance uses condition and performance information to decide when intervention is needed. Neither approach should stand alone. Calendar-based work can prevent basic neglect, while condition monitoring can reveal whether an asset is changing before a scheduled task is due.
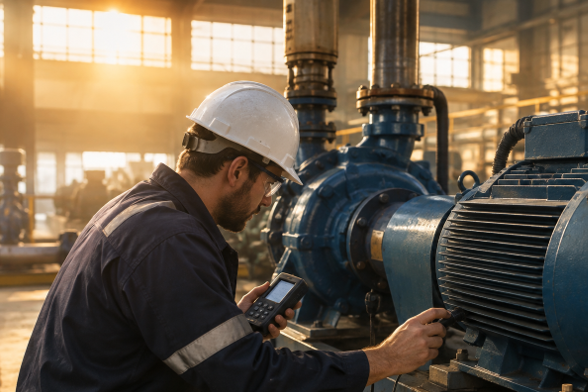
Useful indicators may include temperature, vibration, pressure, flow, motor current, oil condition, and unusual noise. Trend readings, rather than treating each observation in isolation. A technician’s sight, sound, and operating knowledge remain essential, because a sensor value needs context before it becomes a maintenance decision.
Check Common Failure Points
A consistent inspection route makes small changes visible. For rotating and mechanical equipment, check the following items and record abnormalities:
- Bearings, lubrication points, and signs of contamination.
- Couplings, belts, fasteners, and alignment conditions.
- Mechanical seals, gaskets, hoses, and visible leaks.
- Filters, drains, cooling paths, and heat-exchange surfaces.
- Electrical connections, motor condition, and control enclosures.
- Pressure, flow, and temperature readings against normal operation.
- Unusual sounds, odors, movement, rubbing, or vibration.
A minor leak, temperature shift, or new noise is not always an emergency. It is still valuable evidence. Recording changes over time allows technicians to investigate before a small deviation becomes a production-stopping failure.
Improve Spare-Parts Planning
Downtime can continue long after a problem is diagnosed when the required part is unavailable, improperly stored, or incompatible with the asset. Identify parts that can stop critical processes, set reasonable minimum and maximum stock levels, and verify part numbers before an emergency occurs. Bearings, seals, filters, belts, fuses, sensors, and commonly used repair kits often deserve attention.
Store parts according to manufacturer guidance, record supplier lead times and alternate sources, and review obsolete inventory at least twice a year. Purchase decisions should consider total operating cost, not just unit price. A lower-cost substitute can become expensive if it fails early, causes rework, or creates another outage.
Reduce Compressed Air Losses
Compressed air systems need regular attention because leaks, excessive pressure, clogged filters, failed drains, and unnecessary compressor runtime can waste energy and strain equipment. Plants that rely on compressed air to power tools and automation can improve system performance by minimizing leaks and stabilizing system pressure.
Schedule leak inspections, label findings by location and urgency, inspect filters and condensate drains, and compare system pressure with actual process requirements. Also review compressor operation during low-demand periods. Measure pressure, flow, run time, or other relevant readings before and after repairs so the team can confirm whether changes produced a lasting result.
Protect Workers During Maintenance
Fast repairs never justify unsafe repairs. Before servicing equipment, notify affected workers, stop the machine, isolate electrical, hydraulic, pneumatic, mechanical, and thermal energy, release stored energy, and verify isolation. OSHA explains that machine maintenance and repair procedures also require guards and safety devices to be in place and functional before equipment returns to service.
After maintenance, inspect the work area, remove tools and personnel from danger zones, follow the facility’s authorized lockout/tagout process, and communicate before restarting. Safe execution protects people and avoids a second outage caused by incomplete reassembly.
Track the Right Performance Metrics
Completed work orders do not show whether reliability is improving. Review unplanned downtime hours, mean time between failures, mean time to repair, preventive-maintenance completion rate, repeat failures, emergency work as a share of maintenance activity, parts-related delays, and maintenance cost per operating hour. Compare results monthly and focus discussions on patterns that require action.
Create a 90-Day Action Plan
Days 1 to 30: Establish a Baseline
List critical assets, review the previous 12 months of failures, identify repeat problems, confirm maintenance records, and walk the plant with operators and technicians.
Days 31 to 60: Fix Simple Causes
Repair visible leaks, improve access and housekeeping, update inspection checklists, verify lubrication practices, and validate critical spare-parts coverage.
Days 61 to 90: Improve the System
Add condition checks for high-risk equipment, define escalation rules for abnormal readings, coordinate work with production windows, train operators to report warning signs, and review results with operations and maintenance leaders.
Conclusion
Lower downtime usually comes from disciplined, connected improvements rather than a single purchase or software rollout. A clear asset ranking, reliable inspections, prepared spares, safe work practices, and useful performance data help teams find problems earlier and respond with greater confidence. The goal is simple: solve small issues before they interrupt the workday.